Search changes often enough that advice ages badly. The parts that have not changed much are the least exciting ones, which is probably why they get skipped.
This is the groundwork, and — more usefully — how to check each piece of it on your own site rather than take anyone’s word for it. Everything below can be verified in Google’s own documentation and in your own Search Console account.
The key idea
Foundations are not opinions. Every claim in this article can be checked against Google’s documentation or your own Search Console data, and most of the checks are quick to run.
Crawlability and indexing come first
If a search engine cannot reach a page, or has been told not to index it, nothing else about that page matters. That sounds obvious and it is still one of the most common problems on a site that has recently been rebuilt or moved: a noindex left in place from a staging environment, a robots rule blocking a directory, a sitemap still listing retired URLs.
There is a trap here that catches people who are trying to do the right thing. Blocking a page in robots.txt and adding noindex to it are not the same instruction, and doing both cancels the second one out. Google is explicit: for a noindex rule to work, the page must not be blocked by robots.txt and must otherwise be reachable by the crawler, because a crawler that cannot fetch the page never sees the rule. A page blocked in robots.txt can still appear in search results if other pages link to it.
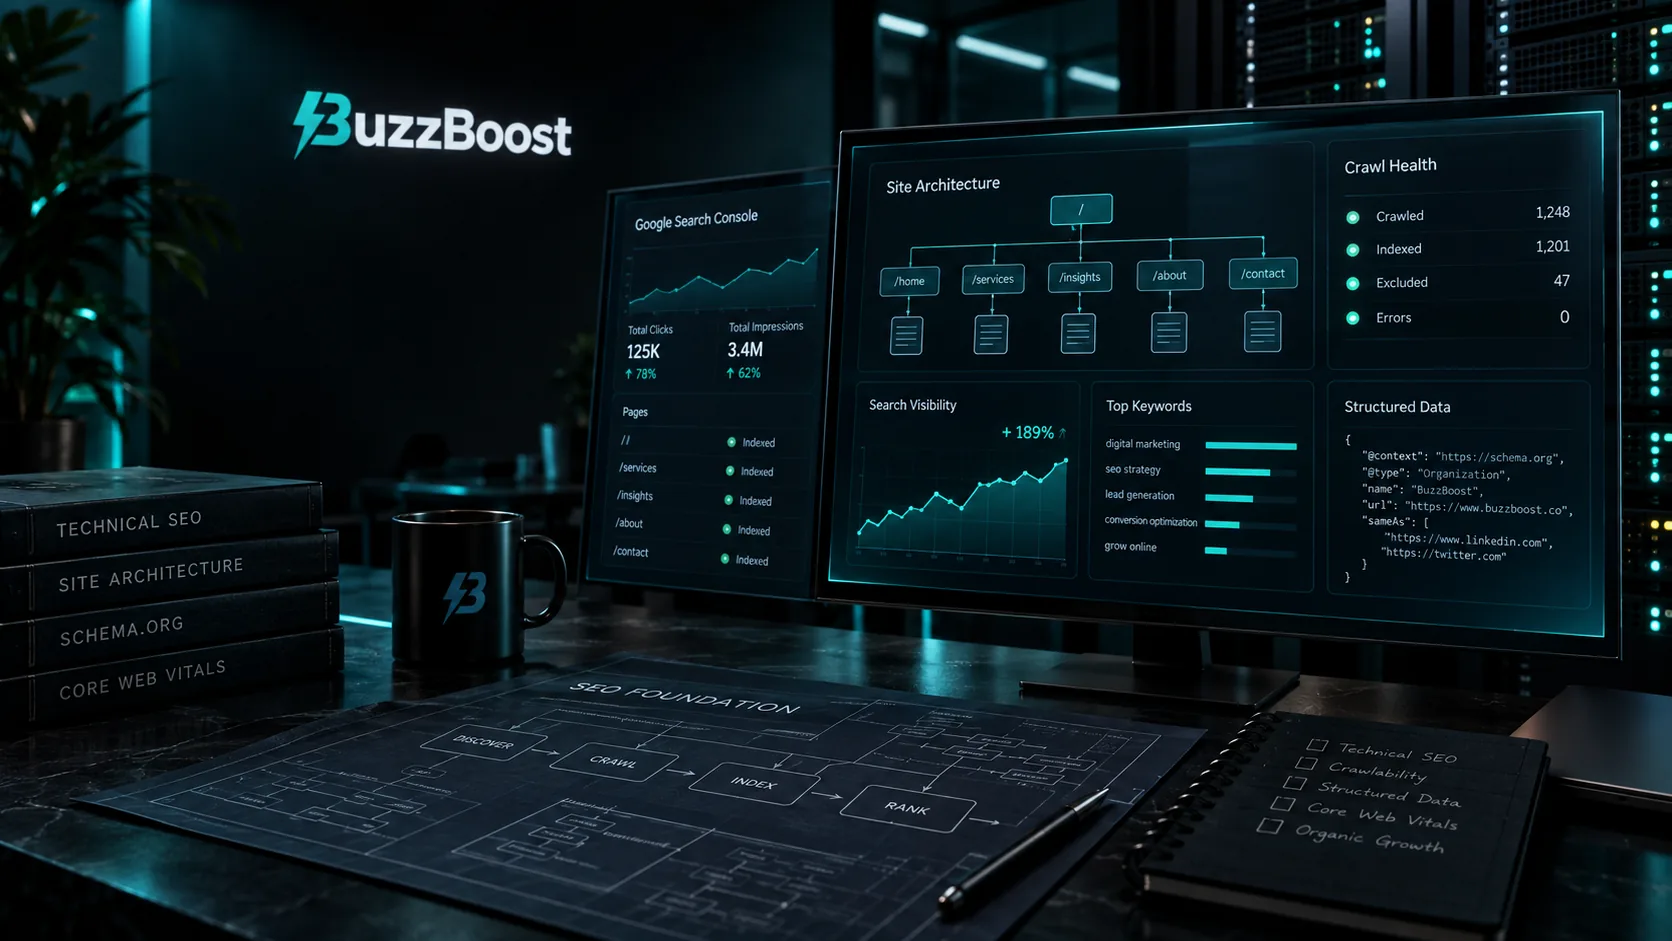
The check: open Search Console and go to the page indexing report. It shows how many of your URLs have been crawled and indexed, and a table of reasons for the ones that have not — server errors, blocked by robots.txt, excluded by a noindex tag, duplicates, not found, redirects. For a single page, the URL Inspection tool gives you the same answer for that URL specifically.
One page per intent
Several thin pages competing for the same topic tend to do worse than one page that covers it properly. It also makes the site easier to explain to a visitor, which is usually a good sign that the structure is right.
The symptom is easy to spot once you look for it: two or three of your own pages taking turns to appear for the same query, none of them settling. The fix is usually to choose the best one, fold the others into it, and redirect them — not to write a fourth.
When we structure a web design project, the page map and the search structure are the same conversation rather than two, because deciding what each page is for is the part that determines both.
Internal links are the part people forget
Internal links do two jobs. They help search engines understand which of your pages you consider important, and they help a visitor get from an article to the thing it relates to. A page with nothing on your own site linking to it is telling search engines something you probably did not intend.
The check: Search Console has a links report with a top internally linked pages table, and you can see which of your pages link to any given page. It is a sample rather than a complete crawl, and it excludes URLs that are not indexed, so treat a page with very few internal links as a prompt to look rather than as proof. Then ask the simpler question by hand: if I only had the navigation and the body copy, could I reach this page at all?
A sitemap is a related but separate tool. Google describes it as a way to help search engines discover URLs and understand the relationships between them, and recommends one particularly for large sites, new sites with few external links, and sites with a lot of video, image or news content. A site of roughly 500 pages or fewer with good internal linking may not need one. Either way, Google is clear that a sitemap does not guarantee that the URLs in it will be crawled or indexed — it is a discovery aid, not an instruction.
Titles, descriptions and headings still do work
A page title should say what the page is about in a way that reads well in a results list. It is worth knowing how Google actually treats it. Title link generation is automated and draws on the <title> element, the main visible title on the page, heading elements, og:title, prominent text and the anchor text of links pointing at the page. Google may replace your title if it detects a problem with it — if it is stale, inaccurate, missing or does not match the page’s language.
Descriptions work similarly. Google says snippets are primarily created from the page content itself, and that it sometimes uses the meta description element instead when that gives a more accurate description of the page. So a good description is worth writing, while accepting that it is a suggestion rather than a setting.
The practical consequence of both is the same and it is slightly unfashionable: the most reliable way to control how your page appears is to make the visible page say clearly what it is about. The tags are a second channel for the same message, not a substitute for it.
Headings should describe the section they sit above, in the order a reader would expect, and there should be one main heading rather than several competing for the role. None of this is clever. All of it is regularly missing.
Speed and stability
Core Web Vitals belong here too, but they are covered properly — thresholds, what each metric means, and why layout shift in particular breaks a page’s path — in why visitors leave, and how a clearer path changes that. There is no sense repeating the numbers in two places where they can drift apart.
A ten-minute check you can run today
In order, because each step makes the next one meaningful. Stop at the first thing that is wrong and fix that before continuing.
Where to start
- Open Search Console and read the page indexing report. Are the pages you care about in the indexed group?
- For any that are not, read the reason given. Blocked by robots.txt and excluded by noindex are different problems with different fixes.
- Run URL Inspection on your single most important page and confirm Google has the version you think it has.
- Search for two of your own pages that cover similar ground. If they take turns appearing, you have one page too many.
- Open the links report and look at the bottom of the internally linked pages table, not the top.
- Read your three most important page titles as they appear in results, not as they appear in your CMS.
- Open the same three pages on a phone and check the first screen still says what the page is about.
None of these checks needs a tool you do not already have. That is rather the point of calling them foundations.
Then the ongoing part
Foundations get you findable. Staying found is a longer conversation about content and relevance, which is what SEO work covers month to month. But it is worth doing in that order, because there is little point publishing steadily onto a structure that search engines find hard to read.
If you would like the foundations checked properly rather than sampled, that is a fixed piece of work with a written result at the end of it.